Data contract platform
Trusted data products,
built by people and AI agents.
Design and deliver data products through executable contracts. Define ownership, enforce quality checks and monitor service levels.
Runs in Google Colab. Nothing to install.
Works with the stack you already run
 Polars
 DuckDB
 Apache Spark
 Databricks
 Microsoft Fabric
 Snowflake
 BigQuery
 Amazon S3
 Azure ADLS Gen2
 GitHub
 GitLab
 Azure DevOps
 Bitbucket
 Jira
 Slack
 Microsoft Teams
 Power BI
 Tableau
Why LakeLogic?
Build data products with clear ownership, quality checks and service expectations. Track whether they deliver.
Discover your data. See what’s missing.
Discover assets, profile data and draft contracts that capture schemas, ownership and dependencies.
- Find assets and their schemas.
- Identify recorded owners and ownership gaps.
- Map declared, imported or inferred dependencies.
- Highlight missing contract information.
Outcome
See what exists, who owns it and what depends on it, so you can assess changes with clearer context.
A simplified view of one page in LakeLogic. The product covers more.
- Defined contracts
- Clear ownership
- Quality controls
- Service levels
- Continuous monitoring
From data contract
to working pipeline.
Design, test and deliver data products on your platform.
Design
Draft contracts from your sources. Review schemas, quality rules and transformations.
Test before delivery
Run against synthetic data in Lakehouse Studio. Inspect accepted rows, failures and their reasons.
Deliver
Create a ready-to-run project for your platform, with contracts, pipeline code and jobs or workflows, opened as a pull request on your repository.
Batch, micro-batch and streaming workloads. Streaming runs on Apache Spark. Engine support
Explore a governed data mesh in action.
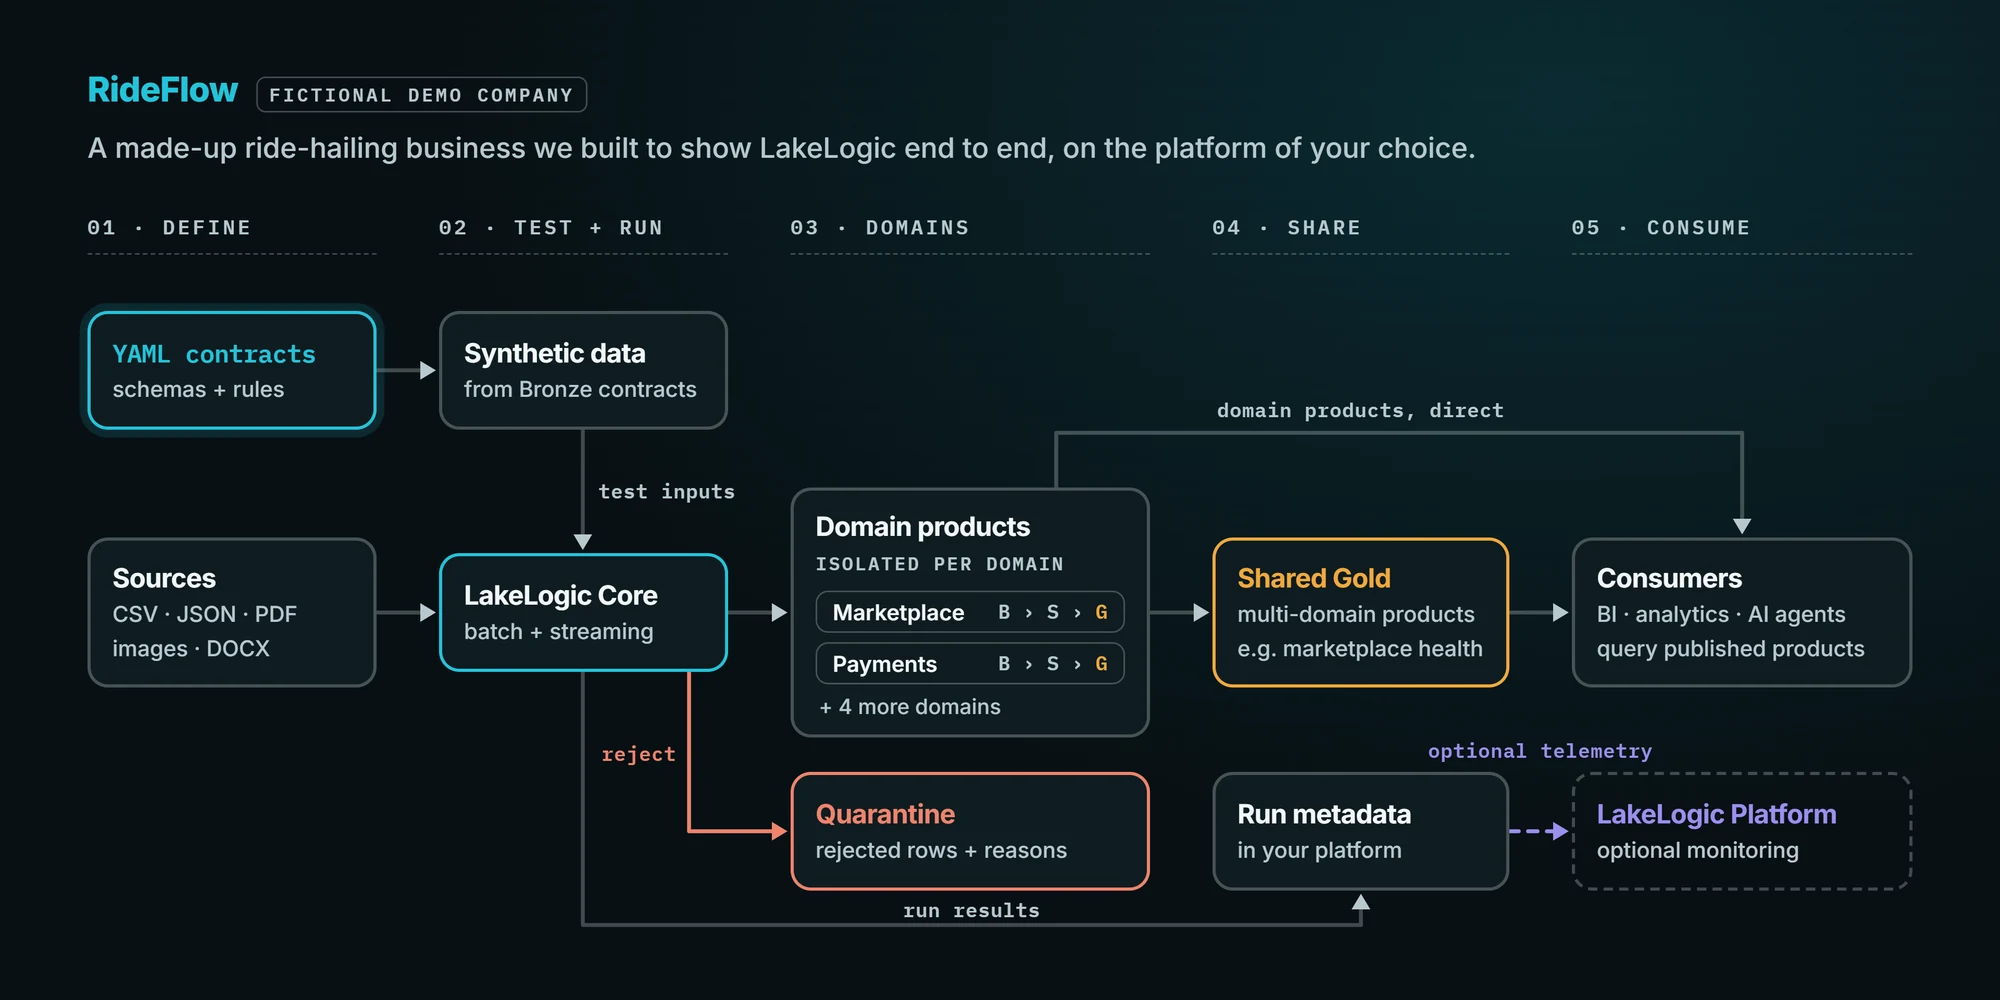
One set of data contracts builds domain-owned data products on Databricks, Microsoft Fabric and Snowflake. Open any project to see its pipelines, its quality checks and the rows they reject.
Microsoft Fabric
A governed data mesh on OneLake, with a lakehouse per domain. Fabric Data Pipelines run each domain from Bronze to Gold, with quality checks and quarantine from the contracts.
Databricks
A governed data mesh on Unity Catalog, with a catalog per domain. Databricks Workflows run each domain from Bronze to Gold, with quality checks and quarantine from the contracts.
Snowflake
A governed data mesh on Snowflake, with a database per domain. Snowflake Tasks run each domain from Bronze to Gold, with quality checks and quarantine from the contracts.


RideFlow uses synthetic data; review each project’s prerequisites before deployment. LakeLogic Core executes supported contracts with Polars, DuckDB and Apache Spark. Compare engine support
Your production data runs in your environment.
Studio can also use samples you choose to upload for design and testing. Use synthetic or appropriately sanitised data.
Production runs in your environment
LakeLogic Core processes production data in infrastructure you control and reports operational evidence to the platform.
You own the contracts
Contracts remain version-controlled in your repository.
You approve changes
Material changes pass through review and your delivery workflow.
Open execution
LakeLogic Core is open source under Apache 2.0, so you can read the code that runs on your data.
Build with us.
Bring a real data engineering challenge. Work directly with the LakeLogic founders to design, test and deliver a governed data product, while helping shape the platform around your needs.
Design partners are early teams who use LakeLogic on a live project and get hands-on support in return for regular feedback. It isn’t a consulting engagement.
Get to know LakeLogic
What is LakeLogic?
LakeLogic is a data contract platform that helps people and AI agents design, deliver and maintain trusted data products. It brings agreed definitions, quality checks and service expectations into the engineering workflow, from testing changes to monitoring production.
What is a data contract?
A data contract defines the agreement between data producers and consumers: the data’s meaning, ownership, quality and service expectations. LakeLogic’s executable contracts also define sources, transformations and how outputs are stored. LakeLogic Core runs the supported processing and checks in your environment.
Does my production data leave my environment?
LakeLogic Core processes production data in infrastructure you control. Only operational metadata, never data values, is sent to the platform for monitoring. Lakehouse Studio also uses samples you choose to upload for design and testing.
Which platforms does it work with?
Explore reference projects for Microsoft Fabric, Databricks and Snowflake. LakeLogic Core executes supported contracts with Polars, DuckDB and Apache Spark. Capabilities vary by platform and engine.
Is LakeLogic open source?
LakeLogic Core, the contract execution engine, is open source under Apache 2.0. The hosted platform adds collaborative design, governance and monitoring.
How do I try it?
Run a sample pipeline in Google Colab with nothing to install locally, or to explore LakeLogic in your own workspace.